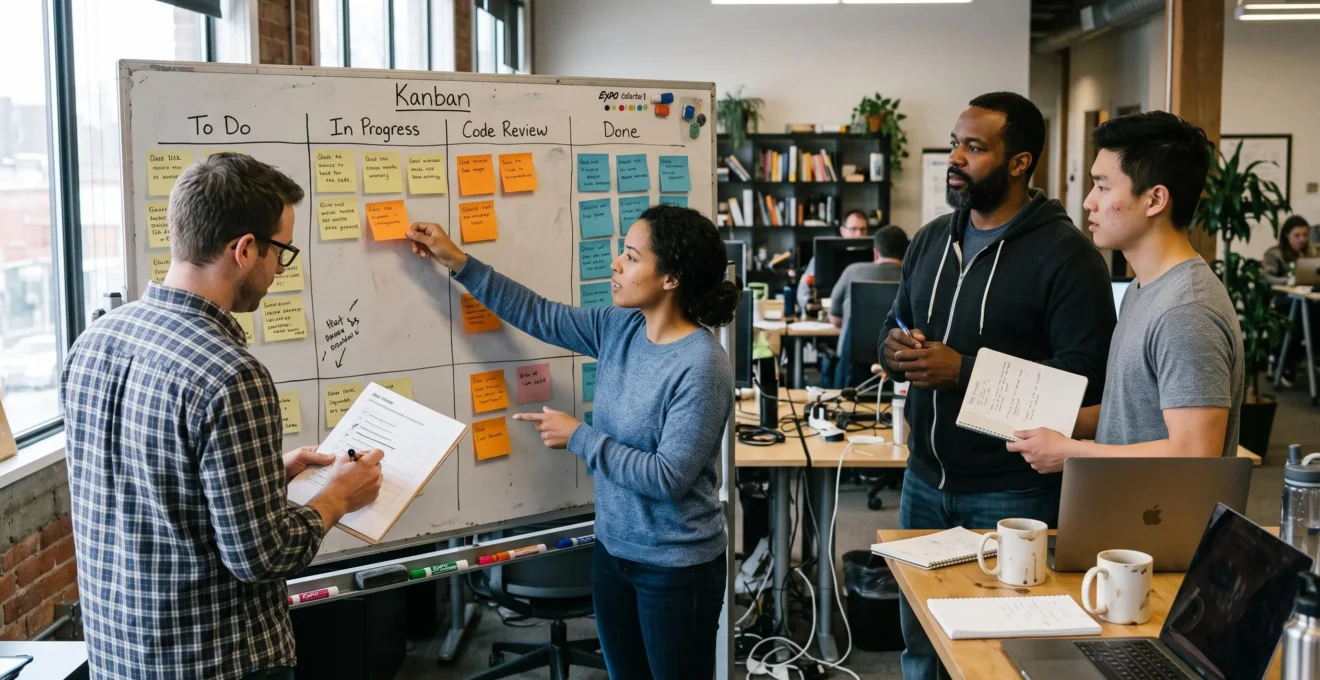
A software team can hold a daily stand-up every morning, plan sprints, run demos, and schedule endless retrospectives without delivering useful software any faster. The core issue is rarely the Agile methodology itself: it is the moment ceremonies degenerate into bureaucratic obligations disconnected from product decisions.
Practicing Agile without bureaucracy means keeping the habits that sharpen decision-making, code quality, and adaptability, while cutting practices that yield no observable improvement. A meeting must unblock work, a sprint must produce a verifiable increment, and a retrospective must change real-world behavior.
For a software engineering team in Canada, this approach also means balancing enterprise governance constraints, client commitments, and unexpected operational support requests. It is not about abandoning planning or metrics, but ensuring those mechanisms remain proportionate to product risk and technical needs.
The difference is visible in daily workflows: fewer tasks started concurrently, independently testable user stories, explicit architectural trade-offs, and project tracking derived directly from developer tools rather than parallel administrative reports.
Core principles of genuinely productive Agile
- Evaluate ceremonies by the decisions they trigger, not by attendance or schedule adherence.
- Structure work around small, testable feature slices while actively safeguarding technical quality.
- Choose Scrum, Kanban, or a deliberate hybrid model based on incoming interruptions and delivery predictability.
- Why Can a Team Follow Every Agile Ceremony Without Becoming Genuinely Agile?
- How to Slice a Complex Feature Without Losing Value for the End User
- Scrum, Kanban, or Hybrid: Which Fits a Team Facing Frequent Interruptions?
- Which Agile Missteps Accumulate Technical Debt Despite Frequent Deployments?
- How to Stop Running Repetitive Retrospectives That Change Nothing Next Sprint
- What Mistake Turns an Iterative Workflow into Directionless Trial and Error?
- At Which Stages Should You Test a Product to Catch Bugs Before They Get Expensive?
- How to Build a Hybrid Approach That Preserves Roadmap Visibility While Staying Adaptable
Why Can a Team Follow Every Agile Ceremony Without Becoming Genuinely Agile?
A team can adhere strictly to every Scrum ceremony without becoming genuinely agile when its meetings trigger zero operational adaptation. Stand-ups, sprint reviews, and retrospectives are formal opportunities to inspect reality and adjust decisions. Their value lies entirely in the changes they produce, not in their calendar frequency.
The Scrum Guide by Ken Schwaber and Jeff Sutherland defines Scrum events as formal opportunities for inspection and adaptation. The Daily Scrum specifically exists to adjust the planned work backlog based on progress toward the overarching Sprint Goal.
Process decay sets in when an organization confuses procedural compliance with real-world effectiveness. The number of meetings held, user stories closed, or ticket statuses updated becomes more visible than the business decisions made and software delivered.
A straightforward test reveals this administrative drift: review the last three occurrences of any recurring ceremony and document what changed after each one.
- Did a sprint review lead to reprioritizing a feature or pruning the backlog?
- Did a daily stand-up clear an active blocker or alter task sequencing?
- Did a retrospective produce a concrete change whose impact was later audited?
If the answers are consistently negative, the ceremony must be redesigned. This does not mean a meeting must force change for its own sake: deliberately confirming a strategy after inspection is entirely valid, provided that confirmation rests on observed evidence.
In large Canadian enterprises, an added friction point emerges when executive management imposes separate project status reporting on top of the team’s operational tooling. Identical metrics are manually re-entered across multiple slide decks and status calls instead of being pulled directly from the team’s primary issue tracker.
The solution is defining the targeted decision, required attendees, and minimal frequency for every ceremony. The schedule must serve team delivery, rather than acting as administrative proof of Agile maturity.
Once ceremonies are refocused on actionable outcomes, the next question becomes practical: how do you break down software work so every cycle yields an observable result?
How to Slice a Complex Feature Without Losing Value for the End User
Slicing a complex feature without gutting its user value requires cutting vertical slices through all architectural layers to deliver an end-to-end user scenario. Each vertical slice must produce observable system behavior—even if functionally narrow—rather than delivering an isolated technical component whose utility can only be evaluated several iterations later.
Consider a hypothetical scenario: a team is building a self-service customer portal for reviewing invoices. A horizontal, purely technical breakdown would allocate one sprint to database schemas, another to API endpoints, and a third to UI styling. Each component might be marked “done” without a customer being able to view a single invoice.
A vertical slice, by contrast, delivers an initial version allowing an authenticated user to view their single most recent invoice, followed by subsequent iterations that introduce billing history, custom date filters, and PDF downloads.
To engineer vertical slices, start from the shortest complete user journey and incrementally expand its functional boundaries:
- Define the concrete user problem the feature solves.
- Draft the thinnest end-to-end scenario that delivers tangible utility.
- Identify the full-stack technical components required to make that scenario functional.
- Layer in edge cases, search filters, and expanded capabilities in follow-on iterations.
Backlog grooming can also separate brief research spikes or UX wireframing tasks from deliverable software slices. However, an exploratory spike must never be presented as working software: its deliverable is an architectural decision, validated knowledge, or a de-risked assumption.
Beware of over-slicing. Splitting user stories into microscopic, disjointed tickets can artificially inflate team velocity metrics while introducing integration bugs, fractured UI experiences, and deferred technical debt.
The governing standard is not the smallest possible story point estimate, but its testable coherence. An end user, product manager, or QA tester must be able to exercise working software under realistic conditions against clear acceptance criteria.
Vertical slicing eliminates software demos with zero working code and sharpens trade-offs, but its success also depends on how the team manages production interruptions and competing priorities.
Scrum, Kanban, or Hybrid: Which Fits a Team Facing Frequent Interruptions?
A software team dealing with frequent, unpredictable interruptions often benefits from adopting a Kanban flow system or a deliberate hybrid model with explicit triage policies. Scrum excels when planned work can be protected around stable Sprint Goals. Choosing the right framework depends on demand predictability and the ability to shield active development cycles.
Scrum structures engineering around time-boxed sprints and committed goals. It establishes a rhythm for planning, review, and adaptation. Contrary to common belief, Scrum does not freeze sprint scope in stone: scope can be clarified and renegotiated with the Product Owner as long as the core Sprint Goal is preserved.
Kanban focuses on optimizing the flow of value, capping Work in Progress (WIP), and establishing transparent service-level policies. The May 2025 Kanban Guide emphasizes visualizing work streams, actively managing flow bottlenecks, and driving continuous process improvement.
To decide, a team can evaluate three operating models against their tolerance for interruptions.
| Criterion | Scrum | Kanban | Hybrid Approach |
|---|---|---|---|
| Predictable Workload | Optimized for cohesive sprint goals | Handled via continuous pull flow | Managed via milestone planning |
| Frequent Emergency Hotfixes | Disrupts focus; requires scope renegotiation | Managed via explicit priority-class swimlanes | Buffer capacity dedicated to triage |
| Primary Metrics | Sprint Goal attainment, velocity | WIP limits, cycle time, throughput | Calibrated to real-world delivery flow |
| Organizational Vulnerability | Blown commitments and developer fatigue | Thrashing priorities without clear WIP caps | Ceremony duplication and metric clutter |
This comparison provides a pragmatic decision aid rather than asserting that one methodology is universally superior.
An engineering team supporting a live production platform while building new features could, for example, reserve dedicated capacity for planned sprint commitments while routing live incident triage through an expedited Kanban swimlane with strict WIP limits.
Problems arise when an organization retains all Scrum ceremonies, layers on all Kanban meetings, and demands both rigid sprint commitments and instant turnaround on production interruptions. This hybrid anti-pattern creates more operational friction than it resolves.
In Canadian public sector or enterprise procurement environments where Scrum is explicitly mandated in contract RFPs, teams must establish clear guidelines with clients regarding sprint change requests, emergency escalations, and acceptance sign-offs.
Regardless of the chosen methodology, accelerating cycle time is dangerous if it comes at the expense of software maintainability and system stability.
Which Agile Missteps Accumulate Technical Debt Despite Frequent Deployments?
Technical debt compounds when an engineering team accelerates delivery by systematically deferring automated testing, refactoring, and foundational architecture cleanups. Software can be deployed to production weekly while becoming increasingly fragile and expensive to modify. High deployment frequency reflects pipeline speed, but guarantees neither system maintainability nor operational stability.
Three development anti-patterns are especially destructive:
- Diluting the Definition of Done. Pull requests are merged and tickets closed when automated test coverage, peer code review, and essential documentation are omitted.
- Perpetually postponing refactoring. Architectural cleanups are treated as optional backlog tickets that are immediately cut whenever new commercial feature requests arrive.
- Piling on tactical design shortcuts. Code is written to satisfy immediate ticket criteria in isolation, ignoring ripple effects on system dependencies, microservices, and future extensibility.
The Definition of Done must enforce non-negotiable software quality standards: comprehensive unit and integration tests, static code analysis, security scans, and verified functional acceptance criteria. It cannot be reduced to simply moving a Jira ticket to “Closed.”
The software delivery performance metrics from DORA explicitly separate delivery throughput (deployment frequency, lead time for changes) from operational stability (change failure rate, failed deployment recovery time). This separation prevents teams from treating raw deployment speed as a complete measure of engineering performance.
However, DORA metrics do not capture all dimensions of technical debt. Engineering teams must also monitor the growing lead time required to touch legacy modules, fragile database dependencies, escalating maintenance overhead, and architectural risk registers.
A proven preventive measure is allocating explicit, non-negotiable capacity for technical debt remediation. The right percentage depends on codebase maturity and system risk: no universal rule fits every engineering team.
This capacity must be tied to measurable outcomes: refactoring a brittle service, retiring an insecure dependency, improving critical-path test coverage, or decommissioning legacy database queries.
Technical debt also acts as a catalyst for deferred organizational bureaucracy. As codebases become fragile, management often responds by introducing manual change advisory boards (CABs), multi-signature approval gates, and defensive coordination meetings. This administrative bloat is the natural result of unchecked architectural decay.
Preserving software health requires an effective collective learning loop, particularly when the same production incidents recur sprint after sprint.
How to Stop Running Repetitive Retrospectives That Change Nothing Next Sprint
To run effective retrospectives, teams must replace sprawling wishlists with one or two tightly scoped process experiments whose outcomes are audited in the very next cycle. Every action item must have a designated owner, an observable behavioral change, and an explicit review date. Without this feedback loop, retrospectives devolve into recurring venting sessions that change nothing.
The classic red flag is adopting vague action items like “communicate better” or “improve cross-functional collaboration.” These capture good intentions, but specify neither the required behavioral shift nor how success will be measured.
An actionable experiment is concrete: “For the next two weeks, any pull request waiting on review for more than four business hours must be flagged directly in our team channel, and we will verify at our next retro whether PR cycle time dropped.”
The designated owner drives the experiment, without being solely responsible for solving systemic blockers. The team can then objectively evaluate what worked, what needs tuning, and what should be abandoned.
A high-impact retrospective follows a tight loop: observe an operational bottleneck, design a scoped process adjustment, run the trial, inspect the empirical results, and adapt. The next retrospective must start by auditing the outcome of the previous experiment before opening new topics.
Ceremony duration and cadence should adapt to team maturity. A stable, high-performing team does not need an identical 90-minute agenda every fortnight. Conversely, an unexpected production incident warrants a focused, deep-dive root cause retrospective.
Some blockers sit outside team authority: third-party vendor dependencies, departmental budget freezes, or conflicting executive priorities. These issues should be escalated directly to decision-makers with a concrete impact statement, rather than repeatedly logged in team retro notes.
The true success metric of a retrospective is not the volume of sticky notes generated. It is the team’s demonstrated ability to alter a workflow and confirm that the adjustment made software delivery smoother.
This operational discipline reflects a core Agile tenet: every development cycle must pursue an explicit product goal rather than generating activity for its own sake.
What Mistake Turns an Iterative Workflow into Directionless Trial and Error?
The mistake is confusing iteration with improvisation. When a team deploys features without forming a testable hypothesis, defining an expected user outcome, or outlining decision gates based on telemetry, development cycles churn without cumulative learning. True iterative development systematically validates, refines, or disproves hypotheses tied to a strategic product vision.
Fast sprint cycles deliver little business value if team direction changes aimlessly every two weeks. Users are confronted with disconnected UI changes, while stakeholders lose visibility into project milestones.
To maintain strategic alignment, every iteration should answer three core questions:
- What user or technical hypothesis are we actively testing in this cycle?
- What empirical observation or telemetry metric will confirm or refute this hypothesis?
- What strategic product decision will we make based on the outcome?
Suppose a team wants to optimize mobile user onboarding. Instead of tweaking visual screens across multiple sprints without a shared baseline, they should test whether removing a specific form field measurably increases completion rates, establishing baseline metrics and evaluation windows in advance.
The product backlog then functions as an ordered portfolio of experiments aligned with the broader product roadmap. It must not degenerate into a chaotic dumping ground of disconnected feature requests or a static Gantt chart disguised as tickets.
Teams must separate the strategic pillars that provide direction from the implementation details open to iterative learning. The core user problem, regulatory parameters, and sprint goals anchor the project. The UI layout, backend service design, and workflow breakdown evolve based on user data.
When this distinction is lost, executive stakeholders lose confidence in Agile delivery and respond by re-imposing rigid Gantt charts and multi-stage sign-off gates. A lack of strategic direction is what ultimately invites bureaucratic oversight back into the organization.
A hypothesis is only as good as the team’s ability to test it against reality—which requires running user and technical tests early in the development cycle.
At Which Stages Should You Test a Product to Catch Bugs Before They Get Expensive?
A digital product should be tested before detailed software architecture begins, on interactive prototypes, throughout active coding, and prior to production cutover. Each testing phase answers a different question: Is the user need real? Is the interface intuitive? Does the code function reliably? And can the release be deployed with acceptable operational risk? Testing must then continue in production post-launch.
The timing of testing matches the nature of the risk. Value risk is mitigated through user research and workflow discovery. Usability flaws are caught via clickable prototypes. Technical defects require automated test suites, static analysis, and end-to-end integration tests.
The guidelines from the Government of Canada on designing with users emphasize discovery research, prototype testing, and continuous feedback integration across public digital services.
For an engineering team, the priority is embedding testing gates directly into development cycles without spinning up a separate QA phase that bottlenecks releases.
Testing early prevents spending developer hours building solutions grounded in flawed assumptions. Correcting an interaction flow on a low-fidelity wireframe costs exponentially less than refactoring production database schemas and backend APIs.
Moderated usability testing reveals where users stumble and why. When participant recruiting is constrained, unmoderated remote tests, session analytics, and customer support ticket trends offer secondary signals, though they do not fully replicate direct user observation.
Embedding testing into engineering in five steps
- Define the core user problem and write a verifiable hypothesis into the backlog ticket.
- Wireframe the primary user flow and draft an observation checklist for usability testing.
- Run usability sessions with representative end users and synthesize observed points of friction.
- Write automated unit and integration tests, enforcing pass criteria in the CI/CD pipeline.
- Track production telemetry post-launch and log a clear decision to retain, iterate, or roll back the feature in the next sprint.
This workflow does not mandate five new meetings. It integrates verification checks into daily engineering, making empirical test results accessible when decisions are made.
When user testing and technical validations feed directly into backlog prioritization, teams can maintain a predictable product roadmap without freezing technical requirements months in advance.
Key considerations for building a hybrid delivery model
- Anchor the team around a stable product goal while keeping implementation paths flexible.
- Define explicit triage policies for how production emergencies enter the workflow and what work they displace.
- Base operational status on working software, system stability, and active blockers rather than manual reporting decks.
How to Build a Hybrid Approach That Preserves Roadmap Visibility While Staying Adaptable
An effective hybrid delivery model pairs medium- and long-term milestones with detailed sprint planning reserved strictly for near-term work. It explicitly separates non-negotiable commitments from implementation variables the team can adapt based on user feedback. Leadership maintains clear visibility over project risks and deadlines without imposing a rigid functional plan on every sprint.
This architecture relies on rolling-wave planning across nested horizons. The macro roadmap defines strategic business outcomes, major cross-team dependencies, and budget boundaries. The near-term horizon defines fully refined user stories ready for active development. Distant milestones remain intentionally broad until real-world data clarifies requirements.
This hybrid structure avoids two classic failures: maintaining an exhaustive Gantt chart that is obsolete within a month, or running a chaotic backlog that prevents stakeholders from anticipating release dates.
To succeed, the organization must differentiate fixed constraints from flexible variables:
- Non-Negotiable Constraints: Contractual milestones, regulatory compliance dates, fixed budget caps, and critical third-party dependencies.
- Adaptable Variables: Feature sequencing, detailed scope boundaries per increment, UI layouts, and underlying technical implementations.
- Governance Rules: Clear authority on who can alter backlog priorities, how production emergencies are triaged, and what trade-offs are accepted when dates slip.
A deadline should never be treated as entirely immutable if scope adjustments become necessary: in such cases, the trade-off must be escalated to leadership for an explicit decision.
Executive visibility should be generated directly from the team’s operational tooling. A live Kanban board, completed story points, WIP throughput, active blockers, and cycle time trends offer a far more dependable foundation for strategic discussions than subjective completion percentages.
The golden rule is eliminating double data entry. Project tracking metrics should be derived automatically from the tools developers use every day to build software.
Executive communication can align with existing sprint reviews rather than spinning up dedicated governance meetings. Strategic, portfolio-level decisions that demand executive trade-offs are handled through formal escalation paths.
A well-architected hybrid model passes two tests: Can a commercial priority shift without blowing up the entire project plan? Can leadership forecast major delivery milestones without micromanaging daily sprint tickets?
If the answer to the first question is no, the delivery model is too rigid. If the answer to the second is no, visibility is broken. Process improvements should target that exact friction point rather than piling on more ceremonies.
The next step is reviewing a recent iteration with the team to eliminate one duplicate reporting task, clarify an emergency priority rule, and define an observable product outcome for the upcoming sprint. These three adjustments deliver immediate agility without requiring a disruptive organizational overhaul.
Can you shorten Agile ceremonies without losing team alignment?
Yes, by ensuring pre-meeting preparation, maintaining live board visibility, and establishing clear decision rules to eliminate circular discussions. A shorter meeting is not automatically better, however. The goal is dedicating time strictly to resolving blockers and making architectural trade-offs, rather than verbally reciting status updates already visible on the board. Teams practicing Scrum must still preserve the core inspection and adaptation objectives of their events.
What metrics track an Agile team’s health without adding manual reporting overhead?
Working software delivered, Work in Progress (WIP) volume, lead time, cycle time, unresolved technical blockers, and change failure rates offer reliable operational telemetry. These can be paired with production telemetry and user feedback. Tracking should focus on actionable metrics that trigger business decisions, rather than turning metrics into individual developer performance targets.
How should a team handle emergencies that arise mid-sprint?
First, qualify the severity of the emergency, assess its business impact, and identify what planned work it will displace. In Scrum, scope can be renegotiated with the Product Owner as long as the Sprint Goal is protected. In Kanban, explicit expedited service policies dictate how urgent tickets preempt standard workflow. In both systems, making the cost of interruption visible prevents the team from taking on incompatible commitments.
Does a small software development team need a full-time Scrum Master?
It depends on organizational complexity, cross-team dependencies, and team maturity. Scrum defines the Scrum Master accountabilities without mandating a dedicated, full-time headcount for every small team. What matters is that someone actively fulfills those accountabilities: removing systemic organizational blockers, mentoring the team on Agile principles, and protecting delivery focus.
How do you know if a new Agile practice is worth keeping?
Before adopting a new practice, define the specific problem it addresses, the observable outcome expected, and an explicit evaluation window. Afterwards, assess whether it improved team coordination, code quality, or delivery velocity without adding administrative overhead. Any practice that fails to deliver measurable value should be modified or abandoned, while ensuring foundational delivery framework rules remain intact.